AI Agent Model Requirements: Tool Calling, Context, and API Compatibility
What It Is
xAgent relies on models for understanding, reasoning, planning, tool calling, and result generation. After deployment, administrators need to configure at least one usable model before users can reliably create sessions and run tasks.
The current version is still beta. Model selection and parameter suggestions will continue to change based on testing.
Basic Requirements
Prefer models with:
| Requirement | Meaning |
|---|---|
| Tool calling | xAgent reads files, calls MCP, executes connector actions, and creates outputs through tools |
| Long context | At least 64k context is recommended; 100k+ is better for long tasks, complex files, and multi-tool workflows |
| Stable reasoning | Stronger reasoning is recommended for Skill creation, long-task decomposition, and complex material handling |
| Stable streaming | Users need to see progress and results during long execution |
| API compatibility | OpenAI API, Gemini API, and Anthropic API are currently supported, but OpenAI-compatible API is the most tested path |
API Support Status
The current version supports:
- OpenAI API / OpenAI-compatible API
- Gemini API
- Anthropic API
Development and testing have mainly used OpenAI API / OpenAI-compatible API. Gemini API and Anthropic API provider compatibility is not fully guaranteed yet. If you have these APIs, you can try them in model configuration and verify chat, streaming, tool calling, long context, and long-task stability.
Context Guidance
xAgent loads dynamic prompts, default tool descriptions, and task context into a session. Earlier development observations reported an initial context near 20k tokens. This is not a fixed startup cost; the version, selected capabilities, and session inputs affect it.
Context has been optimized for prompt-prefix caching. On model services that support prefix caching, repeated system prompts and default tool descriptions can be cached effectively.
Earlier documentation used an approximately 80% context threshold. The public v0.0.21.beta notes specify a 90% request-budget line, with batched summaries of oversized history and active turns. Persistence advances only after all summaries succeed. Request budget is not necessarily the Provider’s advertised window. Compression helps long tasks continue, but it also consumes model capability and may lose details.
Recommended context:
- Minimum: 64k+
- Better: 100k+
- Long tasks, complex files, multi-tool work, multi-round confirmation, and Skill creation: use longer context when possible
Prefix caching reduces repeated fixed-prefix cost, but it does not replace long-context capability. Task materials, tool results, conversation history, and user additions still consume context.
Current Test Notes
The previously documented development environment was resource-limited and mainly tested with Qwen3.6-27B. This is not a recommended production configuration. It is only one model available in the development environment.
Earlier test notes reported that smaller models such as Gemma4-12B have also been tested and can execute long tasks. In real deployment, choose based on task complexity, provider stability, context length, tool calling, and cost.
xAgent will not be limited to one model or one provider. Different models have different strengths. Future model routing and default suggestions will be adjusted based on test results.
Development Test Parameters
The following parameters are development test parameters, not recommended defaults. Actual configuration should follow provider documentation and your own test results.
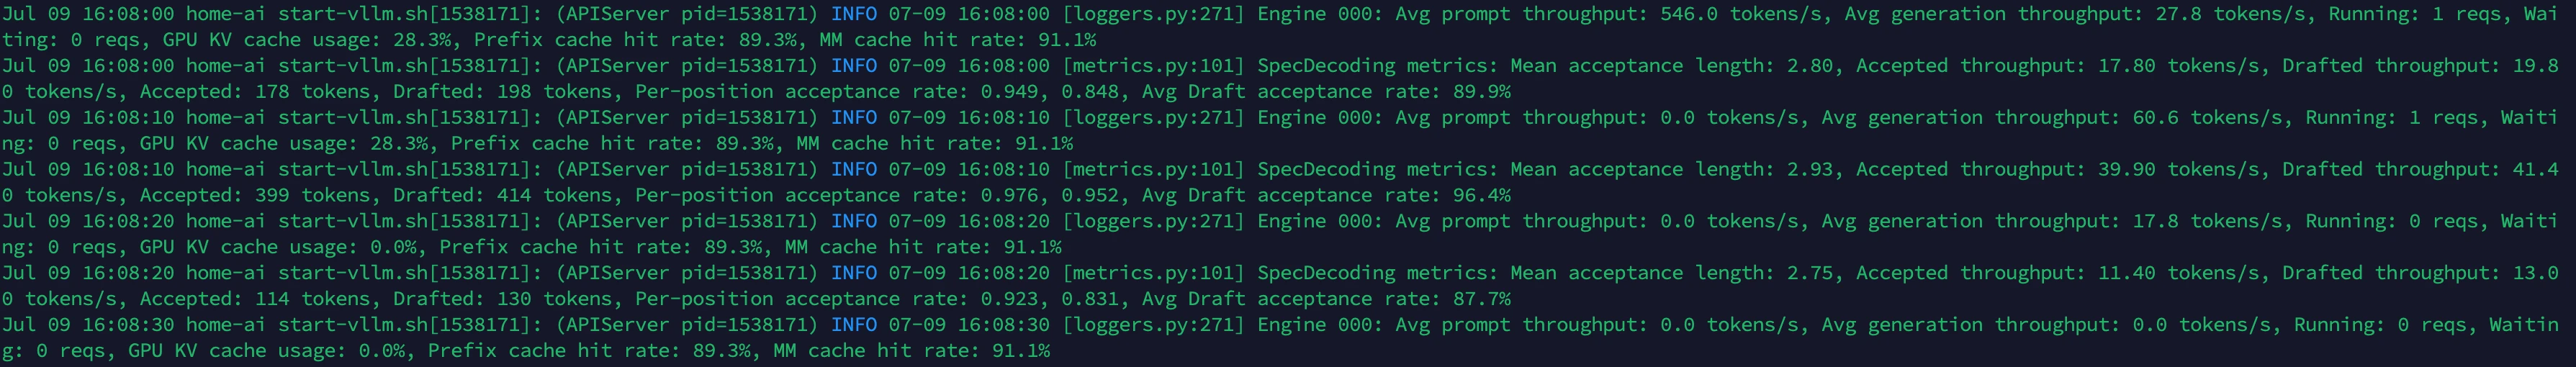
Earlier development observations also recorded prompt-prefix caching, with sample stable sessions reaching 90% or higher. These historical figures are not a general performance promise; actual cache behavior depends on the provider, deployment, and request shape.
{
  "chat_template_kwargs": {
    "enable_thinking": true,
    "preserve_thinking": false
  },
  "max_completion_tokens": 4096,
  "max_context_tokens": 200000,
  "max_tokens": 4096,
  "presence_penalty": 1.5,
  "reasoning_effort": "high",
  "temperature": 0.9,
  "thinking_token_budget": 1024,
  "top_k": 20,
  "top_p": 0.95
}
If your model service does not support a field, remove that field and first ensure stable chat, streaming, tool calling, and long-task execution.
Configuration Checklist
When adding a model:
- Add the model in Model Configuration.
- Test normal chat.
- Test streaming output.
- Test tool calling.
- Create an Agent Session, upload a small file, and ask for an output.
- Test a multi-step task with tool calls.
Only make a model available to ordinary users after it can reliably read files, call tools, generate results, and handle confirmations.