
4 posts tagged with "case-study"

View all tags

How to Coordinate AI Agents: Handoffs and Acceptance in an English Writing Test

· 10 min read

To coordinate AI agents, give each role a bounded assignment, inspect the actual handoff, and check the final result against criteria that do not depend on the agents' own verdict. In this English editorial test, xAgent delegated work to separate Writer and Reviewer sessions and delivered a final report. The Reviewer corrected the word-count breakdown, but approved factual expansions that the supplied facts did not support.

That distinction is the point of this case: the coordination completed; the strict factual acceptance check did not pass.
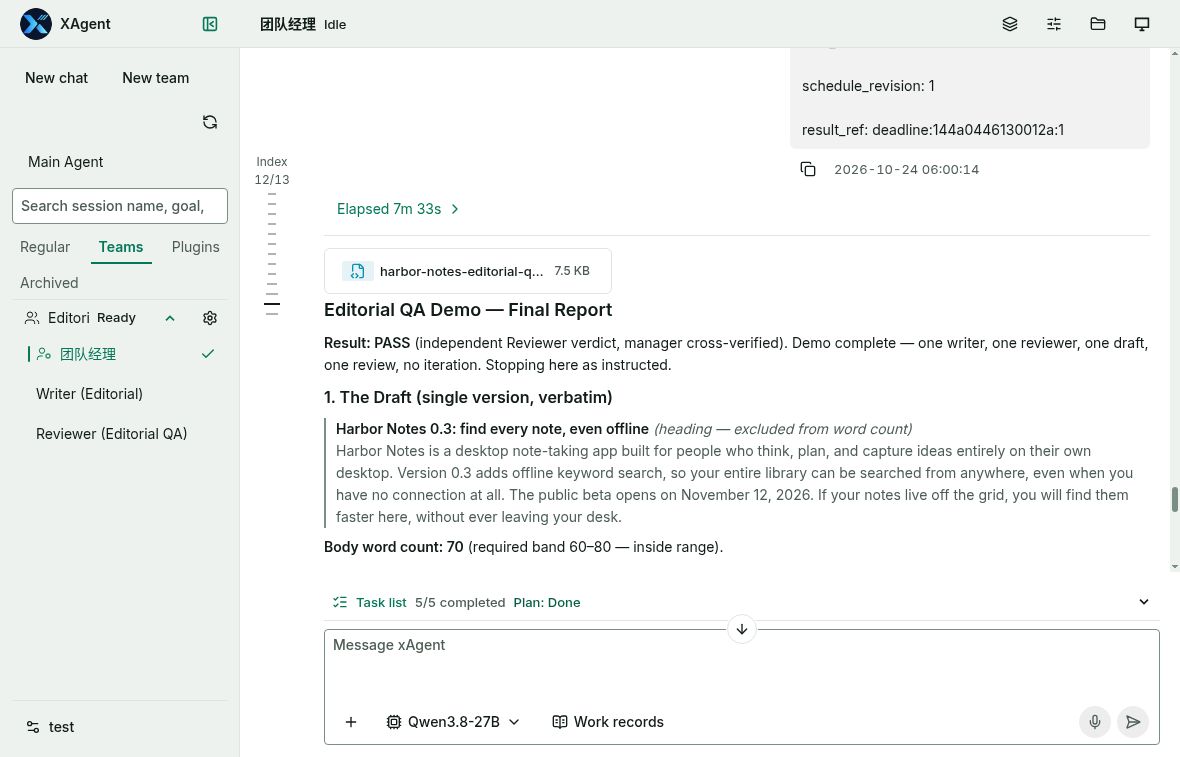
xAgent final English report with the manager Idle, Writer and Reviewer in the sidebar, a 5/5 completed plan, and the system's PASS verdict.

The final screen shows an actual terminal result. PASS is xAgent's verdict, not an independently validated factual-quality pass. The mostly English interface retains the Chinese default manager name. The screenshot is an unchanged browser capture.

From a Goal to an Agent Team: An xAgent Field Test

· 13 min read

Giving a goal to multiple Agents raises practical questions: who owns the goal, who researches, who edits, and who checks the result? Naming roles in a prompt is a start. Seeing what each role actually did is the next step.

On October 23, 2026, we created a separate demo team on the xAgent demo site for a small task using three product facts observed in this UI. This article keeps the real UI evidence and human interventions visible, separating team configuration, task execution and result verification.

xAgent on Moltbook: Account Growth and Recovery Across Long-Running Work

· 8 min read

Karma rose from 10,182 to 18,920, and followers from 200 to 339. The screenshots provide operational records that can be compared across xAgent's work on Moltbook. Meanwhile, cumulative session statistics reached 2.44 billion tokens and 31,035 tool calls. The working materials include an operations manual, a metrics table, reports for individual rounds, and handoff records.

The value of this material lies in the concrete work it captures: how the account changed, how exceptions were handled, and how unfinished work moved from one round to the next. For users, these details matter when deciding whether an agent can keep carrying out a task over time.

I Enabled Wireless Debugging. xAgent and a 27B Quantized Model Did the Rest

· 6 min read

I started with a simple question: if I gave xAgent a test server and a phone, could it route the phone's traffic through the server?

It ended up installing mitmproxy and Frida, connecting ADB and the proxy path, and checking the logs to see which traffic could actually be decrypted. The model behind all of this was Qwen3.8-27B AWQ INT4, a 27B model quantized to 4 bits.

This article follows what happened in order. The server and phone were my own test devices, and all packet capture and debugging took place in an authorized environment.